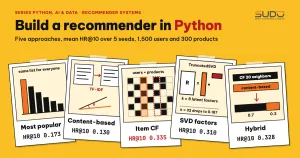
On an online store, a "you may also like" strip under each product is a chance to raise order value, but only if the suggestions are close enough to what the shopper wants. A recommender system answers one question: for this user, out of thousands of products, which 10 should we show? This article builds a recommender from scratch in Python: the most-popular baseline, content-based filtering with TF-IDF, item-based collaborative filtering, matrix factorization (TruncatedSVD and a hand-written ALS), and finally a hybrid. Every number is real output on simulated data with 1,500 users and 300 products, evaluated with leave-one-out.
This article follows Sales forecasting with time series: baselines, ARIMA and gradient boosting, where we learned to always compare against a baseline and never shuffle the time order. For the vector background see NumPy for machine learning: vectorization and broadcasting, and for choosing metrics see Model evaluation for classifiers: precision, recall, ROC and imbalanced data. Environment: a 16 GB RAM machine, CPU only, Python 3.10, NumPy 1.25.1, pandas 2.0.3, scikit-learn 1.3.0. The data is entirely simulated, not real customer data.
Two families of recommender systems: content-based and collaborative filtering
Every recommender belongs to one of two families. Koren, Bell and Volinsky, in Matrix Factorization Techniques for Recommender Systems (IEEE Computer, 2009), split recommender strategies into two broad groups. Content filtering builds a profile for each product or user (category, attributes, demographics) and then matches users to products that fit the profile; its weakness is that it needs outside information that is not always available. Collaborative filtering (CF) relies only on past behavior such as orders, views and ratings, and does not need to know what the product is.
| Family | Data needed | Strength | Weakness |
|---|---|---|---|
| Most popular | Purchase counts | Very simple, a mandatory baseline | Everyone gets the same list |
| Content-based | Product descriptions and attributes | Handles new products (cold-start) | Suggests "more of the same", few surprises |
| Item-based CF | User x product matrix | Easy to explain, precomputed offline | Cannot recommend products with no interactions |
| Matrix factorization | Same as CF | Learns latent factors, compact, suits sparse data | Needs tuning of rank and regularization |
Data and how to evaluate a recommender
We generate 300 products in 6 categories (phone cases, headphones, chargers, mouse and keyboard, home goods, books) and 1,500 users. Each user likes one or two categories and buys 8 to 24 products, with a popularity bias that follows a Pareto distribution. This is implicit feedback: we only know whether a user bought a product, not a star rating.
numpy 1.25.1 | pandas 2.0.3 | scikit-learn 1.3.0

[Catalog] 300 products, 6 categories
 item_id   category                                                          text
       0 phone case phone case silicone genuine compact energy-saving
       1 headphones headphones bluetooth wireless genuine premium cheap
       2    charger charger power bank 10000mAh energy-saving genuine fashionable

[Interactions] 23655 rows | users: 1500 | products with interactions: 300
matrix sparsity: 5.26% of cells have a value
train: 22155 interactions | test: 1500 users (1 hidden product each)
Only 5.26% of the matrix cells have a value; real systems are usually much sparser. The evaluation method is leave-one-out over time: the last interaction of each user is hidden, the model sees only the rest, and we ask whether the hidden product appears in the top 10 recommendations. The first metric is Hit Rate@10 (HR@10), the share of users whose hidden product lands in the top 10. The second is NDCG@10, which rewards the correct product more when it sits higher, using the weight 1/log2(position + 1). Products already purchased are always removed from the list before ranking; the evaluate function in the source code does that.
Offline evaluation is only a rough approximation; only an A/B test on real users tells you whether a recommender actually increases revenue.
Recommender baseline: the most popular products
The simplest baseline counts how many times each product was bought and shows the same top list to everyone. It plays the role of DummyClassifier in the model evaluation article: every serious recommender must beat it.
[Leave-one-out evaluation, k=10, 1500 users, 300 products]
  Most popular (baseline)            HR@10 = 0.157   NDCG@10 = 0.088
Only 15.7% of users have their hidden product in the popular top 10, thanks to the Pareto bias. This is the reference point for every recommender in the sections below.
Content-based recommender: TF-IDF and cosine similarity
For a content-based recommender, we turn product descriptions into TF-IDF vectors (including bigrams) and measure similarity between products with cosine. According to the scikit-learn Pairwise metrics documentation, cosine similarity is the dot product of two L2-normalized vectors, so it equals the cosine of the angle between them, and it is a common choice for comparing TF-IDF documents. The same page notes that when TF-IDF vectors are already L2-normalized, linear_kernel gives the same result but faster, because it does not normalize again.
tfidf = TfidfVectorizer(ngram_range=(1, 2), sublinear_tf=True)
X = tfidf.fit_transform(items.text)
sim_content = cosine_similarity(X)
np.fill_diagonal(sim_content, 0)
TF-IDF: (300, 361) (products x terms/phrases)
3 products most similar to product 0 ('phone case silicone genuine compact energy-saving'):
0.699 phone case silicone genuine 12-month warranty durable
0.698 phone case silicone genuine cheap 12-month warranty
0.643 phone case silicone compact premium genuineThe three nearest neighbors are all silicone phone cases, as expected. To recommend for a user, we add up the similarities of the products they bought: the score of product j is the sum of sim(j, i) over every purchased product i. With a sparse matrix R, that is the product R[u] @ sim_content.
Content-based (profile = sum) HR@10 = 0.131 NDCG@10 = 0.059The result is lower than even the popularity baseline (0.131 versus 0.157). The reason: descriptions contain many shared adjectives ("genuine", "cheap") that give different categories a positive similarity, and a content-based recommender has no idea which products sell well. Its value lies in the cold-start case.
Item-based collaborative filtering recommender
The idea of item-based CF is to treat each product as a column vector of the user x product matrix: two products are similar if the same people buy them. Linden, Smith and York describe how Amazon uses this idea in Amazon.com Recommendations: Item-to-Item Collaborative Filtering (IEEE Internet Computing, 2003). According to the paper, the algorithm builds a table of similar products with cosine in an offline step, so the work at serving time is just a table lookup, and it scales to tens of millions of customers, where user-based CF methods cannot cope.
sim_item = cosine_similarity(R.T.tocsr())      # 300 x 300
np.fill_diagonal(sim_item, 0)

def knn_prune(S, k):                            # keep the k strongest neighbors per row
    S = S.copy()
    idx = np.argsort(-S, axis=1)[:, k:]
    np.put_along_axis(S, idx, 0, axis=1)
    return S

score = R[u] @ knn_prune(sim_item, 20)          # scores for user u
Item-item similarity matrix: (300, 300) computed in 0.002s
Item-based CF, 5 neighbors HR@10 = 0.279 NDCG@10 = 0.161
Item-based CF, 20 neighbors HR@10 = 0.335 NDCG@10 = 0.183
Item-based CF, 50 neighbors HR@10 = 0.338 NDCG@10 = 0.179
Item-based CF, all neighbors HR@10 = 0.339 NDCG@10 = 0.184The item-based CF recommender doubles the baseline: 0.335 versus 0.157. The number of neighbors matters at the low end (5 neighbors is too little information), then saturates from about 20. A catalog of millions of products forces you to cut each row to its top k so the similarity table fits in memory. When you have star ratings, the adjusted cosine variant subtracts each user's mean before computing similarity.
Matrix factorization recommender: TruncatedSVD and ALS
Instead of computing similarity between every pair of products, a matrix factorization recommender learns a latent factor vector for each user and each product so that the dot product approximates the level of interest. Koren and colleagues frame the problem as minimizing regularized squared error over the known entries, and name two main solvers: stochastic gradient descent and alternating least squares (ALS). ALS fixes one side and solves the other with least squares, and according to the paper it suits implicit feedback well, because the training set cannot be treated as sparse, so looping over individual samples as gradient descent does is impractical.
The quickest way to try the idea is TruncatedSVD. According to the TruncatedSVD documentation, unlike PCA it does not center the data, so it runs efficiently on sparse matrices. We project each user into an f-dimensional space, then project back to get scores for every product.
svd = TruncatedSVD(n_components=8, random_state=0).fit(R)
P = svd.transform(R)                  # users in factor space
score = P[u] @ svd.components_        # approximate scores for every product
TruncatedSVD, 8 factors HR@10 = 0.315 NDCG@10 = 0.172
TruncatedSVD, 16 factors HR@10 = 0.275 NDCG@10 = 0.145
TruncatedSVD, 32 factors HR@10 = 0.185 NDCG@10 = 0.094The notable point is that more factors give worse results: 8 factors score 0.315, while 32 factors reach only 0.185. The simulated data has exactly 6 categories, so 8 factors are enough to capture the structure; more factors tend to latch onto each user's individual quirks instead of generalizing (this is a plausible explanation that the article did not test separately). The number of factors is a hyperparameter that must be chosen on a validation set.
Truncated SVD treats empty cells as zeros with the same weight as every other cell. ALS for implicit feedback (Hu, Koren, Volinsky, 2008, cited in Koren's paper) handles this more carefully: each cell has a preference (1 if there was an interaction) and a confidence c = 1 + alpha x r, so cells with interactions are trusted more than empty ones. We implement this method ourselves.
The full code of the als_implicit function is in recsys_demo.py. The trick is to factor out a shared YtY and add a correction only on cells with interactions, so the cost scales with the number of interactions. Each iteration solves each user and then each product with a small linear system np.linalg.solve(A, b) where A = YtY + Yi.T @ diag(c-1) @ Yi + reg*I.
Hand-written ALS: training 2.68s
  Implicit ALS, 16 factors           HR@10 = 0.267   NDCG@10 = 0.135
ALS with 16 factors reaches 0.267, which does not beat item-based CF on this small dataset, and it is untuned (reg, alpha and the number of factors are held fixed). Koren and colleagues report on the Netflix Prize (over 100 million ratings) that factor models beat neighborhood techniques, but that scale is far from the 22 thousand interactions here.
Hybrid recommender and the cold-start problem
When a new product goes on the shelf, it has no interactions, so its column in the matrix is all zeros. This is the cold-start problem. We simulate it: remove all interactions of the last 30 products, then check whether the model puts them in the top 10 of the users who actually buy them (177 users).
[Cold-start] all interactions of the last 30 products removed; users whose test product is in this group: 177
  Item-based CF                      HR@10 (new products only) = 0.000
  Content-based                      HR@10 (new products only) = 0.096
The item-based CF recommender scores exactly 0: it has no way to know whom a new product resembles. Content-based reaches 0.096, low but nonzero because it relies on descriptions. This is the practical reason to build a hybrid recommender that combines the two families: use CF when a product has history and content-based for new products. A simple way is to blend scores after z-score normalization per user.
def zscore_rows(M):
    M = np.asarray(M, dtype=float)
    return (M - M.mean(axis=1, keepdims=True)) / (M.std(axis=1, keepdims=True) + 1e-9)

score = (1 - w) * zscore_rows(R[u] @ sk20) + w * zscore_rows(R[u] @ sim_content)
Hybrid CF20 + content, w=0.0 HR@10 = 0.335 NDCG@10 = 0.183
Hybrid CF20 + content, w=0.3 HR@10 = 0.323 NDCG@10 = 0.179
Hybrid CF20 + content, w=0.5 HR@10 = 0.309 NDCG@10 = 0.169On products that already have history, adding content slightly lowers quality. The weight must depend on context: w near 0 for products with many interactions (measured above), while raising w for new products is a conclusion drawn from the cold-start result, which this article did not measure because the hybrid uses a single shared w.
How reliable is a recommender comparison: running multiple seeds
A single run is not enough to draw conclusions. We rerun the whole pipeline, regenerating the data, with 5 seeds (SEED=42,1,2,3,4) and take the mean and standard deviation of HR@10.
| Model | Mean HR@10 | Standard deviation |
|---|---|---|
| Most popular | 0.173 | 0.018 |
| Content-based | 0.130 | 0.008 |
| Item-based CF, 5 neighbors | 0.268 | 0.016 |
| Item-based CF, 20 neighbors | 0.335 | 0.015 |
| TruncatedSVD, 8 factors | 0.310 | 0.015 |
| TruncatedSVD, 32 factors | 0.187 | 0.010 |
| Implicit ALS, 16 factors | 0.263 | 0.016 |
| Hybrid CF20 + content, w=0.3 | 0.328 | 0.020 |
| Cold-start: content-based (new products) | 0.105 | 0.028 |
| Cold-start: item-based CF (new products) | 0.000 | 0.000 |
The ranking of the recommender models is stable across seeds: item-based CF with 20 neighbors leads (0.335), SVD with 8 factors follows closely (0.310), and both are far above the baseline. The gap between the CF recommender and the hybrid (0.335 versus 0.328) is within one standard deviation, so it is not a real difference. Cold-start fluctuates strongly (standard deviation 0.028) because few users are involved.
When not to use a recommender and common mistakes
- Time leakage: splitting at random instead of hiding the last interaction lets the model "see the future". This is also a mistake covered in the time series forecasting article.
- Forgetting to exclude purchased products: recommending exactly what the customer just bought makes for a poor experience (repeat-purchase goods are the exception and should be treated as a separate problem).
- Popularity bias: a CF recommender pushes best sellers up, and long-tail products are never seen. Measure catalog coverage and diversity too, not only HR.
- Not enough data: below a few thousand interactions, business rules ("buy a phone case, suggest a screen protector") often beat a learned model.
- Personal data: purchase history is personal data; anonymize identifiers and state the purpose clearly in your privacy policy.
To try real data, the GroupLens MovieLens datasets are an academic standard, with a small version of about 100 thousand ratings. That page says redistribution is generally not permitted and each dataset has a README on licensing, so this article uses simulated data that we generate ourselves.
Putting the recommender into a product
For a moderate catalog, the leanest architecture is to compute the top-k neighbor table for each product offline every night, store it in Redis or a database table, and have the website look it up by the product being viewed. When a new product appears, use content-based as a fallback until enough interactions accumulate.
Recommender system checklist
- Before building a recommender, identify the signal: explicit feedback (star ratings) or implicit (purchases, views).
- Always have a most-popular baseline; the recommender must beat it on top-k.
- Split train/test by time and remove purchased products from the list.
- An item-based CF recommender with top-k neighbors is a strong, easy-to-explain starting point.
- A matrix factorization recommender needs the number of factors and regularization chosen by validation.
- Use a content-based or hybrid recommender for new products; set the weight by the amount of history.
- Report the recommender as mean ± standard deviation over multiple seeds; measure coverage and diversity as well.
The full source code is in code/s7-19 (recsys_demo.py, output.txt, seeds_summary.txt, requirements.txt) and runs with python recsys_demo.py. Every recommender number in this article is real output from a 16 GB RAM machine on CPU with scikit-learn 1.3.0; the data is simulated.
Next article
PyTorch basics: tensors, autograd and the training loop. The matrix factorization in this article was hand-written in NumPy; to build deeper models we need a framework with automatic differentiation, and that is the subject of the next article.