A website on Kubernetes gets slower after a few days, occasionally returns 504 and the application log is empty. You open the provider's CPU chart and the nodes sit at only 10 to 20%. Low node CPU does not rule out CPU problems, because individual containers can still be throttled by their limits, but RAM is a hypothesis to examine in parallel. This guide covers a diagnostic method for when you suspect a node out of RAM while CPU stays low: read the overcommit line in kubectl describe node, rule out hypotheses in a controlled way, and understand exit code 137 and the NotReady state. The last section states plainly what has not been proven.
If you just hit a pod that could not be scheduled for lack of CPU, read Pod Pending with Insufficient cpu: calculating real free capacity from kubectl describe node first. This article goes the opposite way: the pods are running, but the node has been given too much work.
Symptoms of a node out of RAM: slow site, low CPU, empty logs
- The admin area is very slow while public pages stay fast. Or both become flaky after a few days.
- The Laravel log has nothing noteworthy at the time of the hang.
- Occasional 504 responses. This symptom has other causes too: a missing or slow dependency (for example a Redis that was never deployed), so do not blame everything on RAM.
The empty log is a clue: if PHP dies because of memory_limit, Laravel usually writes an "Allowed memory size exhausted" error. A silent log suggests the process was killed from outside, for example when the node is out of RAM.
Why a site is slow when node CPU is low: hypotheses to rule out in parallel
CPU and RAM are not interchangeable. With too little CPU, processes run slower but stay alive. When RAM runs out, the kernel has to reclaim page cache, push pages to swap (if any) or kill processes. A node out of RAM can have idle CPU: file reads lose their cache, processes wait for allocations, and the site is slow while the CPU chart shows nothing.
But this is a hypothesis, not a conclusion. A pod with a small CPU limit (say 200m) gets CFS-throttled even when the node uses only 10 to 20% CPU, and that is the classic cause of "slow site but low node CPU". Rule out both:
# Prometheus: ratio of throttled periods for each container
rate(container_cpu_cfs_throttled_periods_total[5m])
  / rate(container_cpu_cfs_periods_total[5m])

# or read inside the container (cgroup v2): a rising nr_throttled means throttling
cat /sys/fs/cgroup/cpu.stat
If the throttle ratio is high, review the CPU limit before you blame a node out of RAM.
Reading describe node to spot a node out of RAM: requests, limits and overcommitted
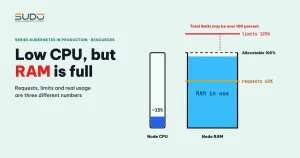
Run kubectl describe node <node-name> and look at the Allocated resources section. An illustrative example for a node with 2 vCPU and 4 GB whose total limits exceed Allocatable:
Allocated resources:
  (Total limits may be over 100 percent, i.e., overcommitted.)
  Resource  Requests      Limits
  cpu       1500m (75%)   2400m (120%)
  memory    2400Mi (62%)  4800Mi (125%)
Three things to read from this block:
- Requests are what the scheduler uses to place pods. Memory requests at 62% mean there is still room, so the scheduler keeps placing pods on the node.
- Limits are the ceiling of each container, and total limits are allowed to exceed 100%. The line "Total limits may be over 100 percent" is the standard Kubernetes overcommit notice, not an error.
- Both are declared numbers, not real usage; real usage is in
kubectl top nodeorfree -m.
Note that kubectl top needs metrics-server; without it you get "Metrics API not available", and you should use Prometheus instead (for example node_memory_MemAvailable_bytes). To run free and dmesg on the node, use kubectl debug node/<node-name> -it --image=busybox and then chroot /host.
RAM overcommit means that if many pods approach their own limits at the same time, the total exceeds the real RAM of the node. Then you have a node out of RAM, and the kernel has to kill processes or the node stops responding. Pods whose request is lower than the limit (the Burstable class) and pods that declare nothing (BestEffort) are the first to lose. BestEffort pods have requests of 0, so they do not raise the requests figure, and the 62% number can hide real usage. For the concepts of control plane, node and pod, see What is Kubernetes: control plane, nodes and pods for PHP developers.
Ruling out hypotheses in a controlled way
When a site is unstable, operators often try many changes one after another. Record them in an exclusion table with neutral remarks instead of rushing to a conclusion, especially when you suspect a node out of RAM:
| Experiment | Result | Remark |
|---|---|---|
| Enable control plane HA | No effect | As predicted: HA covers the API server and etcd, it does not change worker RAM |
| Adjust limits based on Grafana charts | Still unstable | Limits based on charts do not necessarily match peak load |
| Remove cronjobs and queues, drop one node | Admin slow, site fast | May be because the admin pod sits on another loaded node or depends on a slow service; not confirmed |
| Add a node, move workloads over | Admin still slow | The bottleneck may be in a dependency (DB, search) or throttling; measure each component |
Using nodeAffinity to test a hypothesis
To test the hypothesis that "the database sitting next to a heavy workload leaves the node out of RAM", you can temporarily pin a workload to another node with nodeAffinity. The correct syntax is:
spec:
  template:
    spec:
      affinity:
        nodeAffinity:
          requiredDuringSchedulingIgnoredDuringExecution:
            nodeSelectorTerms:
              - matchExpressions:
                  - key: kubernetes.io/hostname
                    operator: In
                    values:
                      - <test-node-name>
This is a testing tool, not an operational configuration: pinning by hostname means the workload can no longer move itself when the node fails. When the test is done, remove the affinity block; removing it and applying again rolls the pods, and the pod does not return to the old node on its own. For a lasting placement constraint, use node pool labels rather than machine names.
A typical scenario: you move the database to a node using less RAM, the RAM chart drops and the site is fine for a while, then hangs again. The RAM drop may come from something else rather than the move, and the renewed hang shows the database's location is not the only cause. Moving both the database and the admin away from the node out of RAM to a node with more memory and still seeing slowness also shows the cause does not lie in a single workload.
Long exec commands killed with exit code 137
A related symptom, though not necessarily caused by a node out of RAM: a long-running command through kubectl exec (for example search indexing) ends with command terminated with exit code 137. The number 137 is 128 + 9, meaning the process received SIGKILL. A common cause is that the container's cgroup exceeded its memory limit and the kernel killed the process, but that is not yet a firm conclusion. Confirm it before raising the limit:
kubectl describe pod <pod> | grep -A3 "Last State"   # look for Reason: OOMKilled
kubectl get events --field-selector involvedObject.name=<pod>
# inside the container, cgroup v2: a rising oom_kill means a process was killed
cat /sys/fs/cgroup/memory.events
# cgroup v1: cat /sys/fs/cgroup/memory/memory.failcnt
# on the node: dmesg | grep -i "killed process"
# while the command runs: kubectl top pod --containers
Note: OOMKilled in describe pod appears only when the container's main process (PID 1) was killed. If only the process started by kubectl exec was killed, PID 1 stays alive, the container does not restart and describe may come back empty; do not conclude it is not an OOM for that reason, read memory.events or dmesg instead.
The exec process runs in the container's cgroup, so it shares the limit with the main process. For example, with a 200Mi limit the command gets 137; raise it to 300Mi and it finishes, but one successful run does not prove 300Mi is enough for all data. If the container runs PHP-FPM, a queue and cron together, the limit applies to the whole container, like the all-in-one image in Dockerizing Laravel: one all-in-one image for Website AI.
Node NotReady under overload
When a node out of RAM is severe, kubelet may not manage to send its heartbeat and the control plane marks the node NotReady. The node controller adds a not-ready or unreachable taint (NoExecute); pods are evicted after tolerationSeconds, 300 seconds by default, so the site is interrupted. If several nodes go NotReady together and the only evidence is "CPU and RAM both overloaded", the cause is still not settled. How to check for yourself when it happens:
kubectl describe node <node-name> | grep -A8 "Conditions"
# look at MemoryPressure, DiskPressure, PIDPressure, Ready and the Message
kubectl get events -A --field-selector involvedObject.kind=Node
The condition MemoryPressure=True is the signal that kubelet is evicting pods for lack of RAM. Read more in the node-pressure eviction documentation.
What is still unsettled about a node out of RAM, and how to do better next time
In many incidents like this, the cause of the periodic hang is never determined. Questions that often stay open for a node out of RAM:
- Whether the RAM is filled by Elasticsearch, MySQL or the monitoring stack. The component using the most on a chart is not necessarily the culprit.
- The evidence usually lacks
free,kubectl topand the MemoryPressure condition, so numbers read from chart screenshots are not reliable enough.
Next time you meet a node out of RAM, collect evidence before guessing. Alert on node RAM at 85 to 90% real usage, track the ratio of total limits to Allocatable for each node, and keep describe node output over time. If you are used to managing RAM on a VPS, comparing with The Database tier: multi-tenant MySQL on small VPS instances shows the same problem: the total declared memory must not exceed real RAM.
Checklist when you suspect a node out of RAM
- If you suspect a node out of RAM, do not conclude from the CPU chart. Check real RAM usage with
kubectl top node(or Prometheus) andfree -m. - On a suspected node out of RAM, rule out throttling with the
cfs_throttledratio alongside RAM. - Run
kubectl describe node: compare requests, limits and the overcommitted line. - Check the Conditions of the node out of RAM: MemoryPressure, Ready.
- List the pods on the node out of RAM and look for BestEffort pods or Burstable pods with large limits.
- Exit 137: check
memory.eventsanddmesgbefore raising the limit. - Use nodeAffinity only to test a hypothesis, and remove it afterwards.
- Set alerts for a node out of RAM and for the ratio of limits to Allocatable.
Next article
cert-manager installation errors: Helm ownership, removed v1beta1 CRDs and the account key. After the node out of RAM, the next article moves on to HTTPS: the common errors when installing cert-manager and issuing certificates on a cluster.