Programming
16 November 2024 16 min read
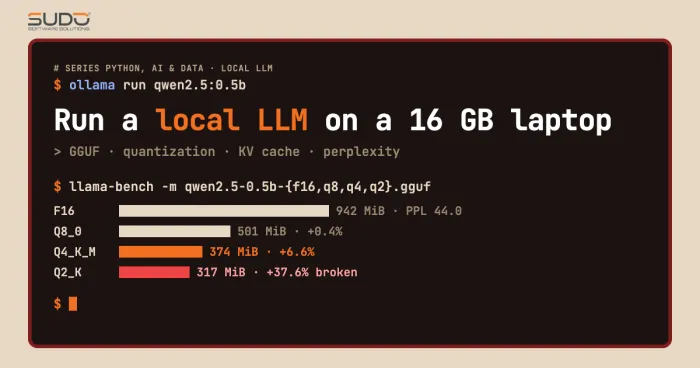
Running a local LLM with Ollama and llama.cpp: model choice, quantization and performance
Sending all of your customer-support content to an outside API is not always allowed, and token bills are not always cheap. Running a local LLM means the model sits on your own laptop or server: the d...