A Kubernetes cluster running hundreds of websites tends to end up in the same state after a while: on paper the cluster is nearly full, the scheduler sees most of the RAM as reserved, some nodes are close to the ceiling, and yet the CPU the websites actually use is only a small fraction of the cluster's vCPUs. This guide walks through a right-sizing process for the CPU and RAM requests of each site: how to measure, which formula to use, how to avoid mixing up numbers when several reports produce different totals, and where adjusting requests stops helping. Right-sizing here is not about cutting costs. It is about reserving what the workload really uses. The examples come from the Website AI cluster on LKE (Linode Kubernetes Engine).
Background on requests, limits and QoS is covered in Requests and limits, QoS and nodeAffinity: placing pods on the right nodes. This article focuses only on measuring and adjusting the numbers.
When you need right-sizing
- The cluster is full on paper: the node's Allocated resources section shows RAM requests well above a safe level, and adding a new site means adding a node soon.
- Real usage is much lower: Grafana shows that the total CPU and RAM used by website pods is only a small fraction of the total requests.
- A few sites are the opposite and exceed their requests: RAM-request threshold alerts fire for some sites, and some sites use several times their CPU request.
- Limits are overcommitted: the total limits on a node far exceed the node's real resources.
The right-sizing process
Step 1: do not rush to raise requests for the sites that alert
The natural reaction to an alert is to raise the RAM request for the sites running close to or above their reservation. That is correct for each individual site, but it can work against the bigger picture. If the cluster is already "full" by requests while real usage is only about a third of node RAM, the problem is not a few sites with too little request. It is that almost every site reserves too much. In that case right-sizing has to go both ways: cut hard for the majority and raise it for the few sites that are short.
Step 2: read requests the way the scheduler sees them
The scheduler only looks at requests, not usage. The numbers it sees are in the Allocated resources section of each node:
kubectl describe nodes | grep -A 8 "Allocated resources"
kubectl top nodes
kubectl top pods -A --sort-by=cpu | head -20
Node-level numbers include system pods and the placeholder DaemonSet. A placeholder DaemonSet that reserves too much RAM on every node makes the cluster look much fuller than it is. How placeholder pods work is explained in PriorityClass and placeholder pods: reserving capacity in a cluster. Check this part before touching website requests.
Step 3: compare requests with real usage
Real usage comes from the CPU usage and memory working set of each pod in Prometheus/Grafana, the monitoring stack described in kube-prometheus-stack: replacing old monitoring and silent misconfiguration. A common pattern looks like this:
| Site group | Request (default at site creation) | Typical usage |
|---|---|---|
| Regular sites (the majority) | 150m CPU, 350Mi RAM | a few dozen millicores, 100–200 MiB RAM |
| RAM-heavy sites (a minority) | 150–200m, 350–450Mi | RAM above request |
| CPU-heavy sites (very few) | 150m | CPU several times the request |
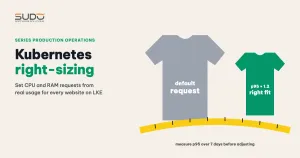
For almost every site, the request is the default value set at creation and has never been measured again. Total CPU requests can be many times higher than real usage.
Right-sizing is not based on usage at a single point in time. Take the p95 over at least 7 days so that peak hours are included:
# Real CPU usage, p95 over 7 days, by namespace
quantile_over_time(0.95,
  sum by (namespace) (rate(container_cpu_usage_seconds_total{container!=""}[5m]))[7d:5m])

# RAM working set, p95 over 7 days, by namespace
quantile_over_time(0.95,
  sum by (namespace) (container_memory_working_set_bytes{container!=""})[7d:5m])
Step 4: apply the right-sizing formula
The right-sizing formula should be simple and easy to explain during review:
# CPU request = CPU p95 × 1.2 + 10m   (round up)
# RAM request = RAM p95 × 1.2         (round up to a multiple of 5Mi, minimum 120Mi)

# example site: p95 around 24m CPU, 116 MiB RAM
resources:
  requests:
    cpu: 39m          # before: 150m (default at site creation)
    memory: 140Mi     # before: 350Mi
  limits:
    cpu: "1"
    memory: 700Mi
The 20% is headroom for fluctuation, and the fixed 10m of CPU gives even a very idle site a minimum reservation. For sites using more than their request, the formula raises the request automatically. Do not raise it halfway (for example, only up to a value that is still below current usage) just to silence an alert.
Step 5: put it in Git as a reviewed change
For a cluster managed with Helm, the new values live in each site's values.yaml. Each right-sizing round should be its own pull request, with a before/after table and the data source. Merge it one group of sites at a time, watch for a few days, then move on to the next group.
A common mistake: many reports, many sets of numbers
When several people report on the same cluster, the totals almost always disagree. The usual reason is that they measure different scopes:
- Website pod level or node level. A node-level report includes system pods and the placeholder DaemonSet, so it is always larger than the total website requests.
- Which branch of the config repo. The numbers on a branch being prepared for right-sizing differ from what runs on the cluster until it is merged and deployed.
- A column filled in bulk. A spreadsheet has a request column with the same value for every site, which does not match the real
values.yaml. - A hand-calculated total row. The total row does not match the sum of its own detail rows.
The cheapest way to know which number to trust: add it up again from the per-site detail table, and state the scope (website pods or the whole node, which branch, at what time) next to every total. Even better, generate total requests automatically from values.yaml and usage from Prometheus, with no manual sums.
Root causes: why right-sizing is needed
- Requests come from the defaults at site creation and are never measured again. The default suits a new site with unknown load, but after several months most sites use only a small part of that number.
- There is no feedback loop from usage back to configuration. Grafana has the real usage,
values.yamlhas the requests, but nothing compares the two. - Placeholder pods reserve too much RAM, so the scheduler sees the cluster as fuller than it is.
- Limits are set uniformly for every site, so total limits far exceed node resources. Right-sizing requests does not fix this part on its own.
After right-sizing: should you consolidate nodes?
Once requests are lowered, the cluster suddenly looks idle and the idea of removing some nodes comes up right away. Do the math first:
- Get the real allocatable RAM of each node (always less than the plan's nominal RAM, because kubelet and the operating system keep a share).
- Add up the new website requests, placeholder pods and system pods.
- Check against N−1 nodes: if one node is lost, the rest must still fit every pod. If the reservation ratio is already above 80–85%, do not consolidate yet.
- Compare total RAM limits with total allocatable. Consolidating nodes raises the limit overcommit ratio accordingly.
Node consolidation is the step after right-sizing. Do it only after the new requests have run stably for a while, not in the same round.
Periodic right-sizing checklist
- Measure over a time window (p95 over 7 days), not at a single point in time.
- Alert in both directions and treat it as a signal that right-sizing is needed: usage above request (risk of eviction when the node is under pressure) and usage below a small fraction of the request for many days (over-reservation).
- Track the ratio of limits to resources on each node. According to the Kubernetes documentation on managing container resources, limits are not guaranteed by the scheduler. RAM limits far above allocatable mean that a few sites growing at the same time are enough to push the node out of memory.
- Review the size of placeholder pods and system pods before adjusting websites.
- Each right-sizing round is a pull request with a before/after table and the data source.
- Schedule it to repeat, for example every quarter or after adding many sites.
Lessons learned
- A request is a promise to the scheduler, not a forecast. Promise too much and you waste nodes. Promise too little and the site gets evicted when the node is under pressure.
- Right-sizing is a recurring task. Site usage changes with content, traffic and code. One adjustment does not stay correct forever.
- Read the scope of every total carefully. Reports disagree because each one measures something different.
- Right-sizing requests does not replace fixing limits. Reservation and limit overcommit are two separate problems, and both need to be handled.
Next article
fastcgi_cache and Set-Cookie: lowering TTFB without leaking sessions. Back to Cloud VPS: turning on real page caching for a site, why nginx refuses to cache every Laravel response, and the price you pay if you allow caching of the Set-Cookie header.