In a multi-tier Cloud VPS setup, the balancer is often the smallest machine but carries the largest responsibility: every website passes through it. When RAM runs out, the kernel triggers the OOM killer, and the largest process on a balancer is almost always nginx. That is an nginx OOM incident: every site behind it stops serving even though the minions and the database are still alive. This article describes a typical case, the step-by-step investigation (including the common wrong leads), the root cause, the fix and the preventive measures.
Symptoms
The situation: a balancer with about 1 GB of RAM and no swap, sitting in front of dozens of websites. One evening, every site behind the balancer becomes unreachable at the same time, and by the time someone notices, several hours have passed. The balancer is the only entry point (see Cloud VPS architecture: Balancer, Minion and Database tiers for hundreds of PHP sites), so when nginx dies here, the healthy tiers behind it are useless. The first status line to read:
$ systemctl status nginx
Active: failed (Result: oom-kill) since ...
Process: ... ExecStop ... code=killed
Result: oom-kill confirms this is an nginx OOM: the process was killed by the kernel for lack of memory, not because of a bad configuration or a crash of its own. If the Duration field shows nginx had been running continuously for days, you can rule out a fault introduced right after a reload.
Investigating the nginx OOM step by step
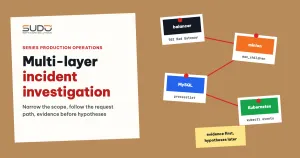
Follow the order from Incident investigation across layers: from balancer to database and Kubernetes: confirm the service state, then resources, then configuration, then traffic.
Step 1: confirm the nginx OOM and check RAM
journalctl -k | grep -iE "out of memory|oom-kill"
journalctl -u nginx --since "-12h"
free -h
swapon --show
If swapon --show prints nothing, the machine has no swap. When memory runs out, the kernel has nowhere to push rarely used pages, so its only option is to pick a process to kill. According to the Linux kernel vm sysctl documentation, the OOM killer picks the process with the highest "badness" score, which is mostly based on how much memory it holds. On a balancer, that is almost always nginx. Save the output of journalctl -k right away, before the logs rotate: the kernel memory table printed at kill time is the most valuable piece of evidence.
Step 2: read nginx.conf after the nginx OOM
worker_processes auto;
events {
    worker_connections 16384;
}
keepalive_timeout 65;
client_max_body_size 64M;
Be precise here: worker_connections is only a ceiling on concurrent connections per worker; nginx does not preallocate buffers for that many connections. A calculation like "workers × worker_connections × buffer size" is not the RAM actually in use. The problem with a large value is that it limits nothing on a 1 GB machine: as real connections grow, each one brings its own buffers, and no layer stops them before RAM runs out.
Step 3: traffic before the crash
# count requests per hour in the access log (combined format)
awk '{print substr($4, 2, 14)}' /var/log/nginx/access.log | sort | uniq -c | tail
If the request count spikes in the hour or two before nginx was killed, there are two familiar suspects: a scraping bot, or one site with abnormal traffic.
Step 4: the loudest suspect is not necessarily the culprit
Count requests in each site's log file; the top site often reveals a suspicious client:
awk -F'"' '{print $6}' /var/log/nginx/site-a.example.access | sort | uniq -c | sort -rn | head
awk '{print $9}'      /var/log/nginx/site-a.example.access | sort | uniq -c | sort -rn
A common situation: a vulnerability scanner knocking on Tomcat Manager and JBoss, trying to download backup files. It sounds very much like the culprit. But if most of its requests get an immediate 404 with a response of a few hundred bytes, and that site's byte volume was actually falling before the machine died, it cannot be what exhausted RAM. A source of nginx OOM must have traffic that keeps growing right up to the last minute.
Step 5: find the nginx OOM source by measuring bytes
This is the decisive step. Field 10 in the combined log format is the number of bytes sent to the client ($body_bytes_sent). Sum it per site within the suspect time window:
WINDOW='<dd/Mon/yyyy:HH>'     # time window before nginx was killed
for f in /var/log/nginx/*.access; do
  total=$(grep "$WINDOW" "$f" 2>/dev/null | awk '{sum+=$10} END{print sum+0}')
  [ "$total" -gt 0 ] && echo "$total $(basename "$f")"
done | sort -rn | head
Usually there is a site with fewer requests than the loudest one but far more data transferred, meaning each of its responses is very large.
Step 6: inspect the site sending the most bytes
# URLs with responses larger than 1 MB
awk '$10 > 1048576 {print $10, $7}' /var/log/nginx/site-b.example.access | sort -rn | head
# status code distribution
awk '{print $9}' /var/log/nginx/site-b.example.access | sort | uniq -c | sort -rn
Typical signs: .m4v or .mp4 video files of several MB going straight through the reverse proxy, many 206 Partial Content responses (the browser downloading byte ranges), along with 499 when viewers seek or close the tab. Byte traffic that keeps growing until nginx is killed makes this the prime candidate for the nginx OOM.
Root cause
An nginx OOM incident of this kind is usually the result of three factors at once:
- Serving large files through the proxy. Videos and downloads go through the balancer, with many concurrent sessions.
- No swap. There is no buffer between "RAM almost full" and "the kernel kills a process".
- Configuration with no realistic ceiling: large
worker_connectionsandkeepalive_timeoutallow a great many connections, each held for a long time.
Be careful with the conclusion. According to the nginx proxy module documentation, when proxy_buffering is on, each connection only keeps a fixed number of buffers in RAM and the rest is written to a temporary file on disk. The traffic passing through is not equal to the RAM nginx holds. If the kernel memory table at kill time was not saved, record this only as a "strong suspicion", not as "confirmed".
The long outage after the nginx OOM is a separate cause. The nginx systemd unit from the Debian package does not set Restart=, so once killed, nginx just sits in the failed state. If a self-healing layer like the one in Low-cost self-healing: detecting and restarting dead services does not cover the balancer, or itself runs on the machine that is out of RAM, nothing brings the service back.
Fixing the nginx OOM
Temporary
Restart nginx, check that the sites behind the balancer respond normally, and save the kernel log. This brings the service back but fixes nothing: the conditions that caused the nginx OOM are still all in place.
Add swap to small-RAM machines
Swap is the cheapest way to make sure an nginx OOM is no longer the kernel's first reaction.
An idempotent script that creates a swapfile of half the RAM, at least 512 MB and at most 1 GB, with vm.swappiness=10 so the kernel only uses swap when it really needs to:
[ -f /swapfile ] && exit 0
TOTAL_RAM_MB=$(awk '/MemTotal/ { printf "%d", $2/1024 }' /proc/meminfo)
SWAP_MB=$(( TOTAL_RAM_MB / 2 ))
[ "$SWAP_MB" -lt 512 ]  && SWAP_MB=512
[ "$SWAP_MB" -gt 1024 ] && SWAP_MB=1024

fallocate -l "${SWAP_MB}M" /swapfile || dd if=/dev/zero of=/swapfile bs=1M count="${SWAP_MB}"
chmod 600 /swapfile && mkswap /swapfile && swapon /swapfile
grep -q '/swapfile' /etc/fstab || echo '/swapfile none swap sw 0 0' >> /etc/fstab
echo 'vm.swappiness=10' > /etc/sysctl.d/99-swappiness.conf
sysctl --system
Let systemd restart nginx automatically
A small override, following the systemd.service documentation:
# /etc/systemd/system/nginx.service.d/override.conf
[Service]
Restart=on-failure
RestartSec=3s
Then run systemctl daemon-reload. Automatic restart does not replace investigation: on the next nginx OOM the service comes back within seconds, but there must still be an alert so operators know it was just killed.
Reduce load and set ceilings
- Move videos to object storage or a CDN, so the balancer only serves HTML and small assets.
- Lower
worker_connectionsandkeepalive_timeoutto levels that suit a small machine, based on measured concurrent connections (stub_status), not on gut feeling.
Preventing nginx OOM
- Every balancer and minion with less than 2 GB of RAM should have swap to avoid an nginx OOM when load spikes. Check regularly with
swapon --show. - Alerts must come from outside the machine: HTTP probes against a few representative sites on each balancer. If nginx dies, that machine cannot report it itself.
- Check
systemctl show nginx -p Restarton every important machine. - Add the byte-counting
awk '{sum+=$10}'snippet to the incident runbook. - Review sites that serve large media files through the proxy and plan to move them out.
Lessons
- Do not trust request counts, measure bytes. When investigating an nginx OOM, the loudest client is usually not the culprit. The culprit is often a site with few requests but responses weighing several MB each.
- A machine without swap has no buffer. Swap does not make a machine faster, but it turns "dies instantly" into "slows down", which leaves enough time for alerts to fire.
- The systemd default is no restart. Do not assume an important service will come back on its own.
- The balancer is a single point of failure. One nginx OOM takes down every site behind it. The measures above only lower the probability; they do not remove the risk of a single-balancer design for the whole cluster.
- Record the wrong leads too. Ruling things out usually takes the most time, and that is exactly what teaches you to measure the right thing.
Next article
PHP-FPM hang: following strace to a synchronous S3 call. A PHP-FPM pool full of busy workers with almost no traffic, and how to trace from a file descriptor to the exact line of code waiting on the network.