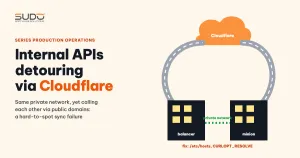
A very common architecture as a system grows: the central application and satellite websites sit on the same private network, yet call each other's APIs through public domains, which means going out to the Internet, through Cloudflare and only then back to the balancer. Everything works fine until that public hop degrades in waves: the sync monitoring board shows timeout errors, data between headquarters and the stores lags, product pages hang, while the private network keeps running perfectly. This guide shows how to narrow down this kind of failure by matching individual requests across several log sources, ruling out hypotheses one by one, comparing against another balancer, and why the solution is to take internal APIs out of Cloudflare.
Context and symptoms
The example in this article is a multi-store retail system on Cloud VPS in a single datacenter: the central sales management application (called HQ) and the store websites sit behind balancer A; the main e-commerce website sits behind balancer B and calls HQ's inventory and order APIs. Both balancers are behind Cloudflare, and balancer B will be used as the control group.
A full check usually finds more affected flows than the dashboard shows:
- HQ → stores: errors on the dashboard, customer data syncing slowly.
- Stores → HQ: receipts, invoices, orders and inventory reaching HQ late.
- E-commerce website → HQ: product pages call the sync API while rendering, so customers wait until the timeout.
- Users → Cloudflare → balancer A: the share of 499s (client gave up) rises noticeably during the bad minutes.
The callers share the same distribution of cURL errors: mostly cURL 28: Operation timed out ... with 0 bytes received, followed by Connection timed out, and a few Recv failure: Connection reset by peer.
Investigation process
Step 1: are errors spread evenly or in waves?
Group errors by minute. In this kind of incident, errors arrive in waves, each lasting from one minute to nearly half an hour, and within the same minute requests to many stores on many different PHP-FPM pools fail together. That suggests the cause lies in a shared hop, not in individual sites.
Step 2: match each request across three log sources
The main method is to trace each failed request through three places, using the sync record's ID as the key: the sender's Laravel log, the receiver's Laravel log (the Webhook | received and UPSERTED ... tmp_key lines), and the balancer access log (written once the response has been sent). A prerequisite: the machines' clocks are NTP-synchronized. The results usually fall into two groups:
- Group 1: the receiver finished processing, but the response never reached the sender. PHP received the request after a second or two, processed it in a few dozen milliseconds, the balancer logged the response as sent, and yet the sender still timed out.
- Group 2: the request never reached the origin. No trace at the balancer or in PHP; the receiver only sees the retry that came later.
[T+0s]   INFO:  [SyncWebhook] UPSERTED customers | tmp_key: 1_298553          (store)
[T+13s]  ERROR: [SyncService] sendTo CONNECT_ERROR
    | URL: https://store-02.example/... | cURL error 28: Operation timed out after 15000 milliseconds   (HQ)
Note: some requests report Connection timed out even though PHP received them very quickly, so that curl message cannot be used on its own to narrow things down.
Step 3: rule out the usual suspects
The first suspect is usually PHP-FPM hitting max_children, especially when a small store minion carries many pools. Check it by correlation: does a failed request have a max_children warning on that same pool within ±10 minutes, and do the daily max_children counts move in the same direction as the sync errors? If most failed requests have no matching warning, and the two series move in opposite directions, rule this hypothesis out.
The other hypotheses are ruled out with one-minute Prometheus samples for exactly the bad minutes:
- Balancer, minion and database CPU are low; CPU steal is near 0. Completely different from the case in Phantom 100% CPU from the hypervisor: when top does not tell the truth.
- Packets into the balancer are at baseline; the NIC shows no errors or drops; no OOM, no
ListenOverflows, no SYN cookies. - conntrack was never full (
early_drop=0); the firewall has no limiting rules; the nginx error log has noupstream timed out. - The private network is stable: Prometheus scrapes over it did not lose a single sample.
nstat -az | grep -E 'ListenOverflows|ListenDrops|SyncookiesSent'
cat /proc/sys/net/netfilter/nf_conntrack_count /proc/sys/net/netfilter/nf_conntrack_max
ip -s link show eth0
Step 4: compare with another balancer that is also behind Cloudflare
When callers from many different IP ranges all fail at the same time, the only thing they have in common is that the destination sits behind balancer A. To tell whether the problem lies with Cloudflare in general or only with the path into balancer A, compare the real user traffic of balancer A with balancer B (same datacenter, also through Cloudflare) during the bad minutes against the surrounding baseline: the bad-minute-to-baseline traffic ratio and the share of 499s. If only balancer A loses traffic and gains 499s, the problem is on the path into balancer A and affects real users too; it is not a general Cloudflare outage or a datacenter-wide problem.
Step 5: outside information, and the limits of the investigation
- Compare with the Cloudflare incident history and the VPS provider's maintenance notices. A coincidence in time is not proof.
- From inside the infrastructure, you usually cannot tell whether the failing hop is Cloudflare → the balancer's public IP or the provider's uplink for that specific IP. Finding out requires Cloudflare Analytics data for the zones (52x rate, origin response time) and a ticket with the provider listing the bad time windows.
Root causes
| Layer | Details |
|---|---|
| Trigger | The public hop between Cloudflare and the balancer degrades in waves: slow connections, stuck responses, resets. The source lies outside our own infrastructure |
| Root cause (architecture) | A large daily volume of API calls between machines on the same private network goes through public domains, the Internet and Cloudflare. The internal flows depend entirely on a hop nobody controls |
| Amplifier (code) | The sync sending function uses one shared timeout for both connecting and reading, with no connect_timeout and no short retry. The e-commerce website calls the API while rendering the page |
| Not the cause | PHP-FPM max_children, server resources, nginx, the firewall, conntrack, the database, the private network |
On data safety: if every sync receiving endpoint upserts by key (tmp_key) rather than adding or subtracting quantities, then group 1 requests (written but treated as failed and sent again) do not create duplicate data; they only cost extra requests and false error reports. Verify this before enabling retries.
Remediation
Quick fix: map the domains to the balancer's private IP
If the balancer listens on 443 on every interface, calling the private IP directly still matches the certificate (the domain name stays the same, SNI does not change). Test from every group of calling machines: ssl_verify_result=0, and connection time under 1 ms instead of hundreds of milliseconds through Cloudflare. Check that webhook authentication does not depend on the source IP. If the machine runs no DNS cache and nsswitch is files dns, /etc/hosts takes effect immediately:
# on the HQ minion (back up first)
cp /etc/hosts /root/backup_hosts_$(date +%Y%m%d)
cat >> /etc/hosts <<'EOF'
# call internal APIs through balancer A, without detouring through Cloudflare
10.0.0.24 store-01.example store-02.example store-03.example
EOF

getent hosts store-02.example                       # must return 10.0.0.24
curl -sI https://store-02.example | grep -i server  # no more "server: cloudflare"
Rolling back means copying the backup file back. The cost is manual maintenance: adding or moving a store requires editing /etc/hosts.
Durable fix: configuration in code
Put the internal IP in an environment variable and use CURLOPT_RESOLVE to force the resolution, with separate timeouts:
// config/sync.php
'internal_ip' => env('SYNC_INTERNAL_IP'),   // empty = use public DNS as before

$host = parse_url($url, PHP_URL_HOST);
$options = ['connect_timeout' => 3, 'timeout' => 15];
if ($ip = config('sync.internal_ip')) {
    $options['curl'] = [CURLOPT_RESOLVE => ["{$host}:443:{$ip}"]];
}- Retry 1–2 times with a 1–2 second backoff on cURL errors 28, 35 and 56 before recording a failure, but only if the receiver upserts by key.
- E-commerce website: cache inventory and new order results for 30–60 seconds and lower the timeout, so pages do not hang when the API is slow.
Taking Cloudflare out of the internal API path solves the machine-to-machine flows and the false "written but reported as failed" errors. It does not solve the real user flows that still go through Cloudflare; that part needs to be clarified with Cloudflare and the provider.
Prevention checklist
- Architecture rule: server-to-server calls within the same private network use the private network. Cloudflare is for users coming from the Internet.
- Logs good enough to narrow things down: add
$request_timeand$upstream_response_timeto the balancer'slog_format. - Active probes on both paths: from the monitoring machine, call the same endpoint through Cloudflare and through the private IP, and compare latency and error rates. A sudden gap is a sign the public hop is in trouble.
- Protect the origin: restrict ports 80/443 on the balancer's public IP to Cloudflare's IP ranges and the private network only. Before tightening, move every domain that still points directly at this IP behind Cloudflare.
- API calling code always has a separate
connect_timeout, bounded retries and caching where possible, like every network call in the request path.
Lessons learned
- Calling internal APIs through Cloudflare adds an unnecessary dependency. The private network worked fine throughout the incident, but no flow used it.
- Matching each request across several log sources distinguishes "never arrived" from "arrived but never came back", something curl's error messages do not tell you accurately.
- A control group is the cheapest way to narrow things down. A balancer in the same datacenter, behind the same Cloudflare, unaffected, immediately rules out "Cloudflare is down".
- Acknowledge the limits. From inside the infrastructure you cannot see the hop between Cloudflare and the provider; the conclusion must say "undetermined" until there is data from both sides.
Next article
Infrastructure maintenance checklist and technical debt management. The final article of Series 3 and of the whole three-series set: what to do daily, weekly, monthly and quarterly, and how to manage technical debt.